PROJECT STUDY · FINAL-YEAR PROJECT · 2022
From curated data to an imagined character
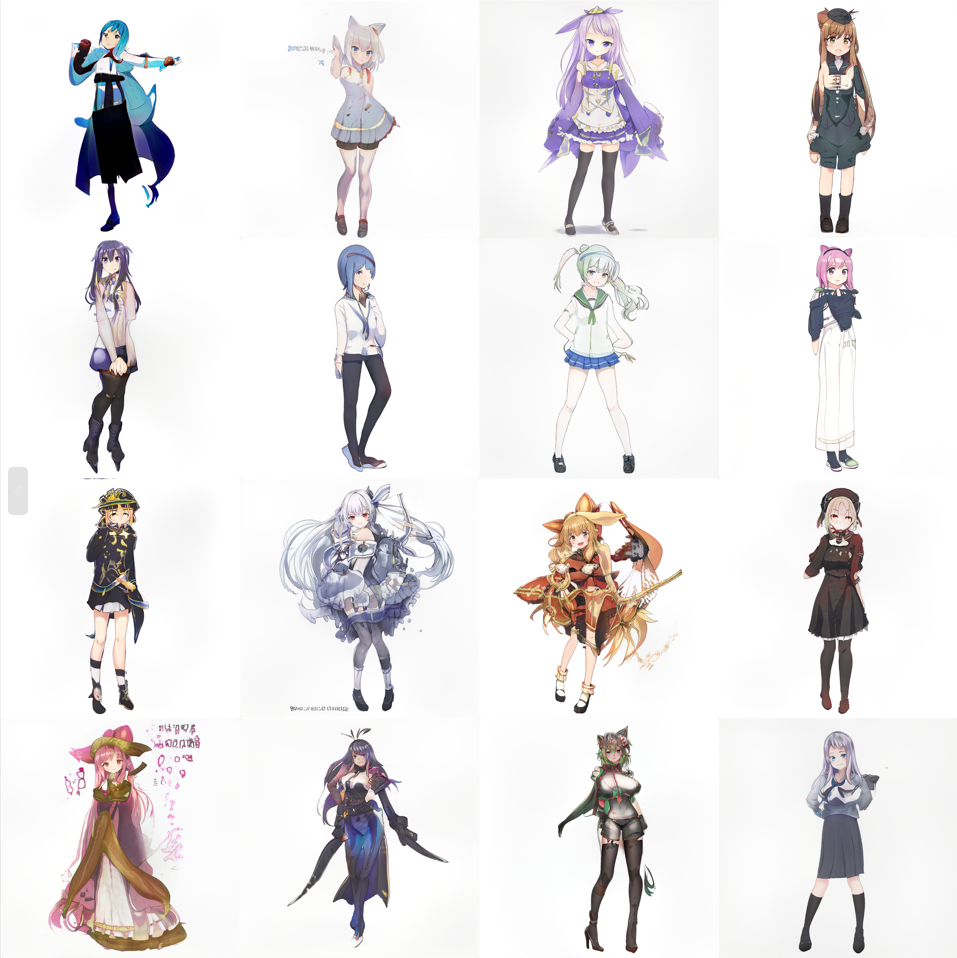
I trained a 512 × 512 anime StyleGAN2 model from a dataset I curated. This page summarizes what the presentation documents and separates it from the recovered model that runs in the browser.
The reported benchmark is from the final-year presentation. It is not independently reproduced here, and the browser demo does not retrain the model.
What the project records
- I curated an anime illustration dataset, then trained a 512 × 512 model using Diffusion-StyleGAN2 with DiffAugment.
- The presentation specifies 512-dimensional Z/W latents, batch size 32, R1 gamma 5, and zero path-length regularization and style-mixing probability, using an RTX 3060.
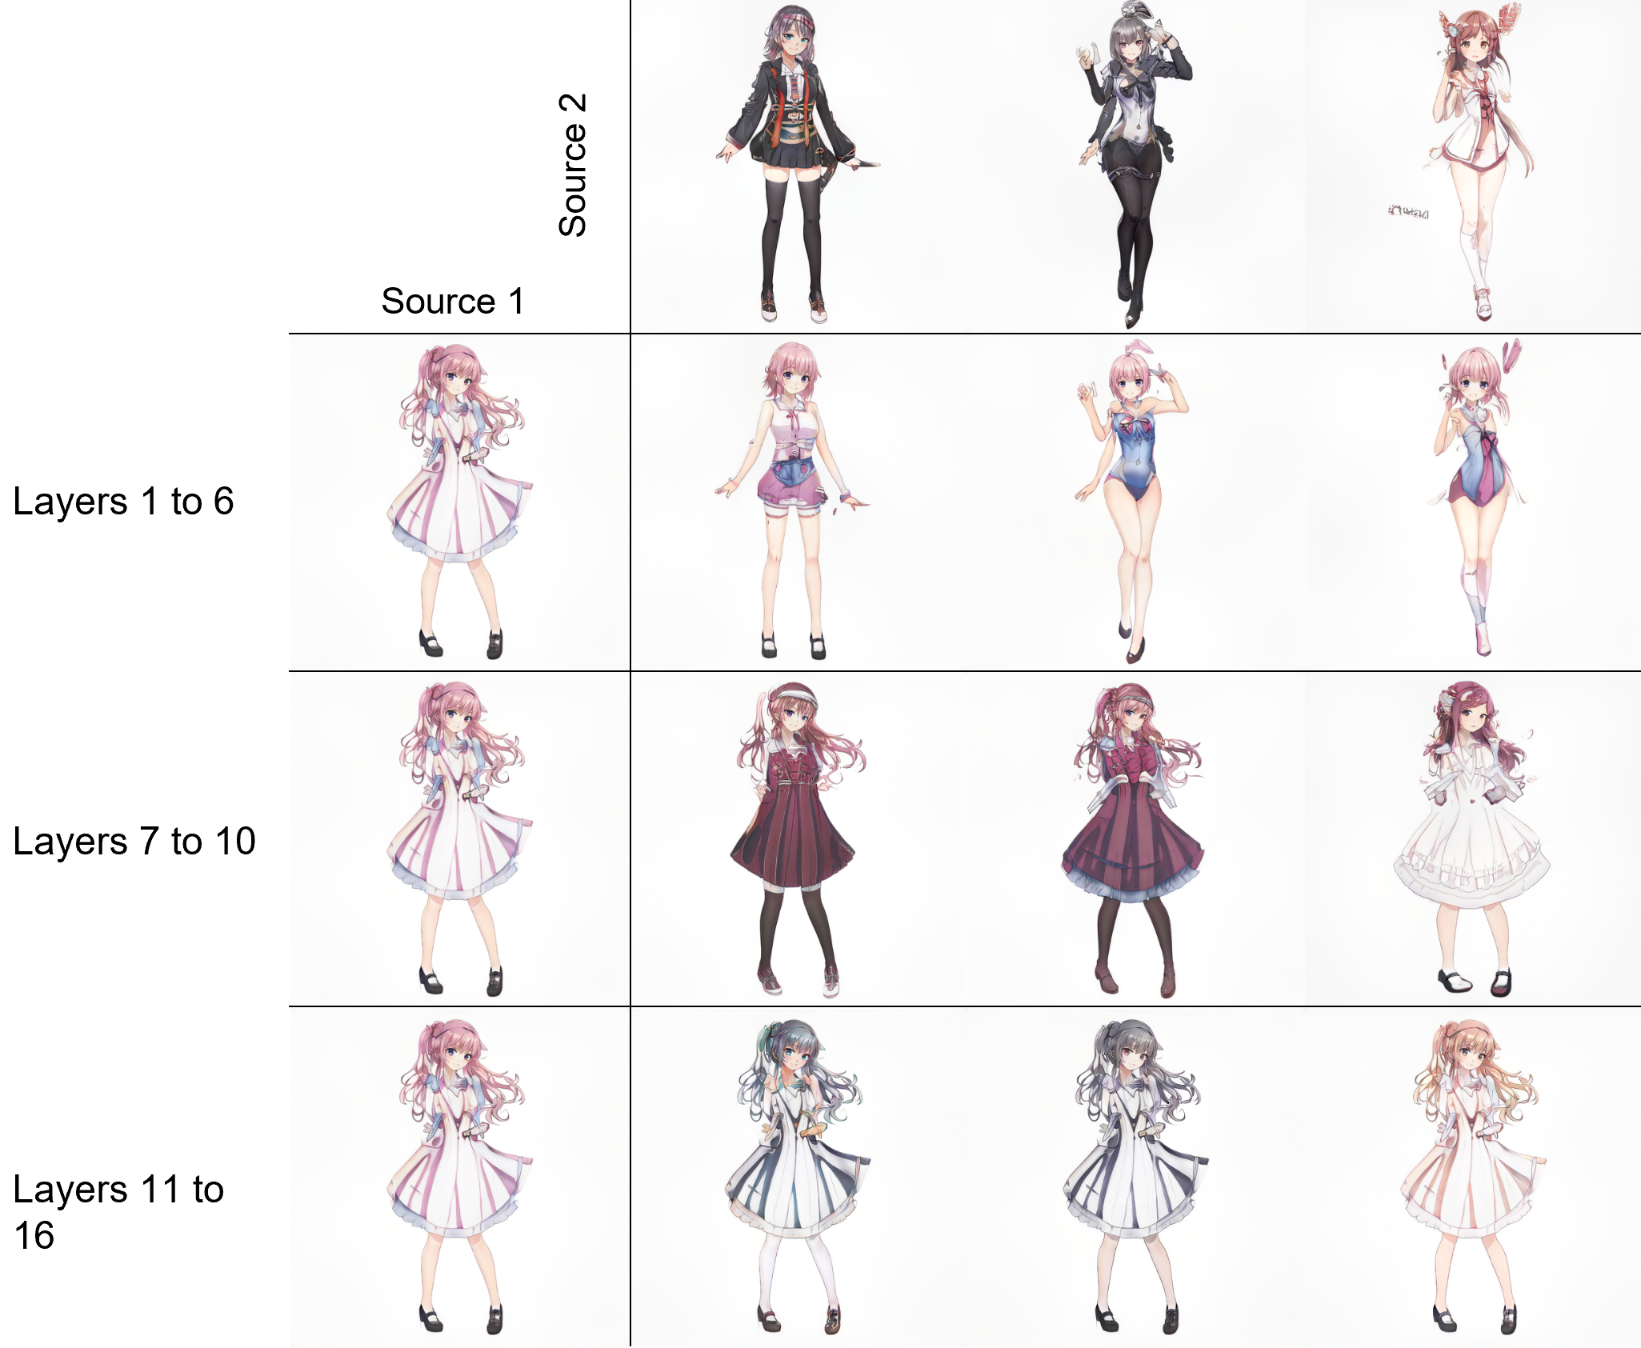
- I explored style mixing and GANSpace edits, then used generated images as inputs to Waifu Diffusion. The StyleGAN-NADA examples used a separate pretrained model.
What the evidence cannot settle
The presentation reports FID 7.73 and includes generated samples, but does not provide the evaluation logs, the full evaluation protocol, or a controlled stability comparison. I no longer have the original checkpoint hash, conversion tool and version, or exact noise settings, so I cannot establish that the recovered browser export is byte-for- byte the checkpoint behind that reported score.
The orbit at the top of the homepage is a pre-rendered walk through recovered model outputs, not a recording of training. The live demo runs inference from that recovered export; it does not reproduce training or rerun the benchmark.
See the presentation evidence · Try the recovered model · Public project record and abstract